
Multi-Touch Attribution: Measuring the Full Customer Journey
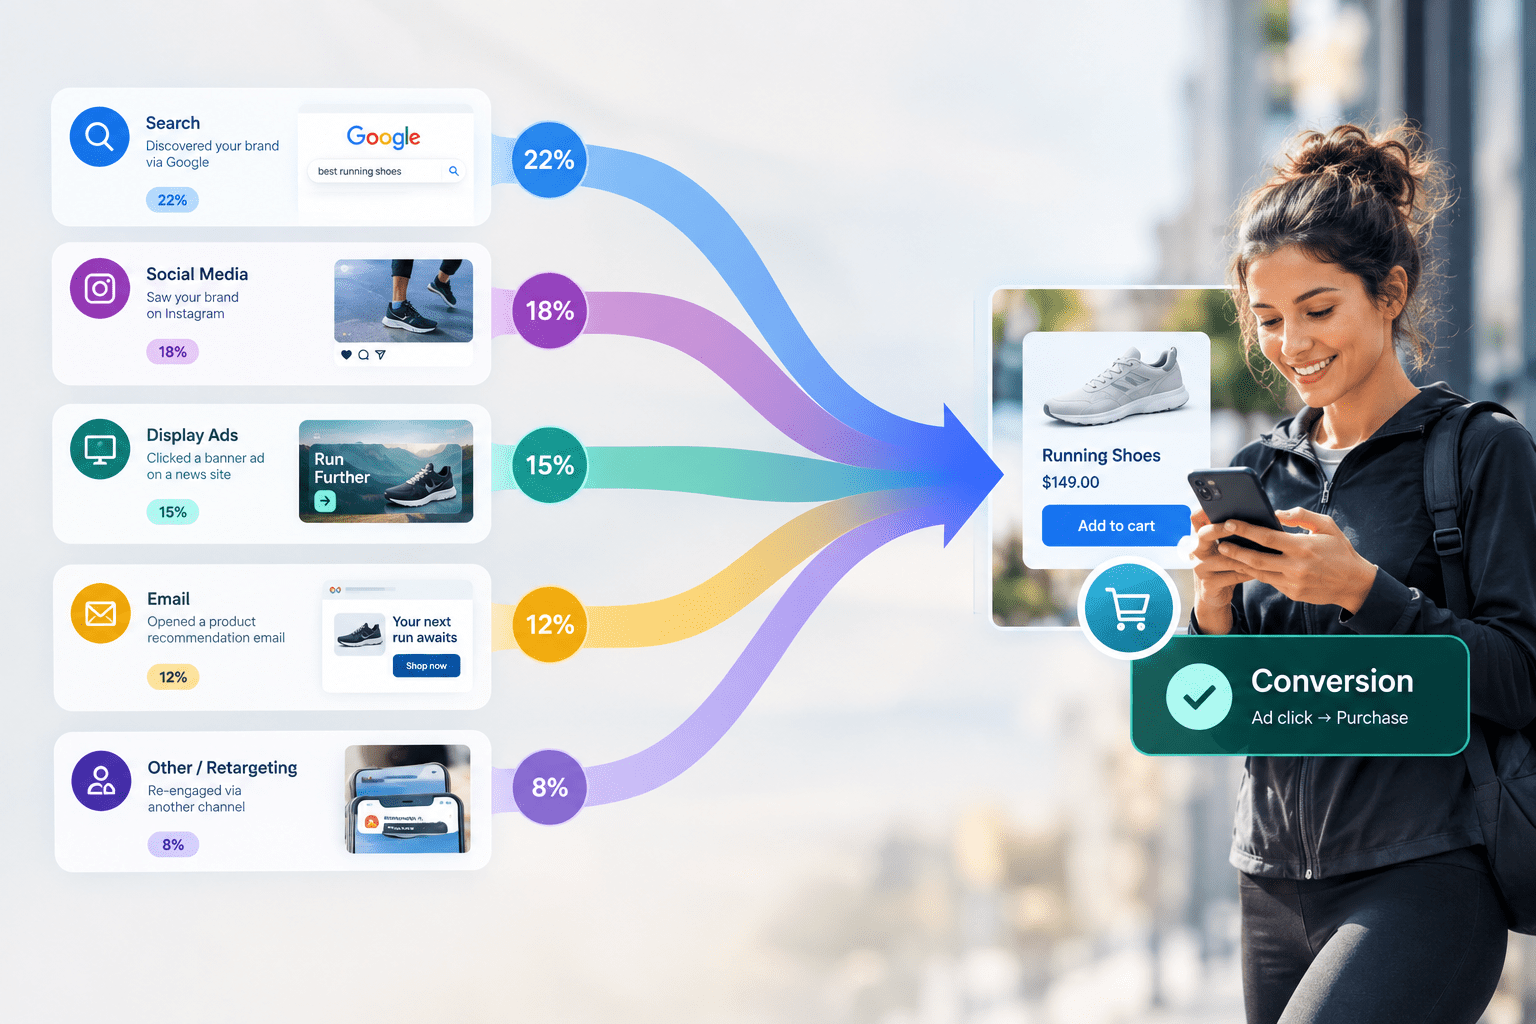
Multi-touch attribution splits credit for a conversion across every touchpoint that contributed to it, instead of handing it all to the last click. The model you choose gets most of the attention. The blind spots deserve more of it.
Last-click attribution gives one touchpoint all the credit for a conversion and ignores everything that led up to it. Multi-touch attribution (MTA) tries to fix that by distributing credit across every touchpoint in the path. That’s a genuine improvement over last-click. It’s not the complete picture most vendor decks imply it is.
What MTA actually measures
MTA tracks the sequence of marketing touchpoints, an impression, a click, an email open, a retargeting hit, that a customer interacts with before converting, and applies a rule to split credit for that conversion across them. The output is a channel-by-channel or campaign-by-campaign view of contribution, which is what makes it more useful than last-click for budget allocation: it stops a display retargeting campaign that closes deals started elsewhere from either getting 100% of the credit or none of it.
What it doesn’t do is prove causation. MTA measures correlation across a tracked path. Whether the customer would have converted anyway, with or without any given touchpoint, is a question MTA structurally can’t answer, and that gap is exactly where incrementality testing earns its place alongside it, not instead of it.
The models, and why the choice matters less than the caveats
| Model | How it splits credit | Best for |
|---|---|---|
| Linear | Equal credit to every touchpoint | Simple baseline, early-stage measurement maturity |
| Time-decay | More credit to touchpoints closer to conversion | Short sales cycles |
| U-shaped (position-based) | Heavy weight on first and last touch, less in the middle | Valuing both awareness and closing |
| Data-driven (algorithmic) | Machine learning assigns credit based on actual observed impact | High-volume, well-tracked funnels with enough data to train on |
The honest answer to “which model should we use” is that the difference between a reasonable model and a slightly better one is usually smaller than the distortion caused by what MTA can’t see at all, which is the next section. Picking a defensible model and moving on beats spending a quarter debating time-decay versus U-shaped.
Where MTA breaks down in a cookieless world
MTA was built for an environment where a shared identifier could stitch a path together across channels and sessions. That environment has been shrinking for years. Safari’s Intelligent Tracking Prevention and Apple’s own privacy-preserving attribution frameworks limit exactly the kind of cross-site tracking MTA depends on for anything touching Safari traffic, and walled gardens like the major social and retail media platforms increasingly report on their own attribution logic rather than exposing raw path data at all.
The practical effect is that MTA increasingly measures the parts of the journey that happen to still be trackable, not the whole journey it claims to measure. A path that includes a Safari session, a retail media impression on a closed platform, and an in-store visit will show up in MTA as a much shorter path than what actually happened, because the untrackable legs simply don’t exist in the model’s view.
Need to put a number on your next media decision?
Model the impact of a media or marketing decision on your own numbers, browse the full library of strategic calculators and decision tools, and get definitions straight on the industry terms that come up along the way, three free resources, ready whenever you need them.
When MTA is worth building, and when it isn’t
MTA earns its keep when most of the journey genuinely happens in trackable digital environments you control, search, owned email, your own site, and the volume is high enough for a data-driven model to have something real to learn from. It earns its keep less when a meaningful share of the journey happens offline, on closed platforms, or on Safari, where the model’s picture is structurally incomplete regardless of how well it’s built. In that second case, MTA still has a role, just a smaller one: treat its output as one directional input, paired with incrementality tests and, where the offline share is large, the matching methods covered in Offline Attribution: Measuring Marketing Impact in the Physical World, rather than the single source of budget truth.
What Apple’s Private Click Measurement (covered in What Is Apple’s Private Click Measurement) does for Safari specifically is a useful illustration of the broader pattern: platform-level privacy measurement is filling in some of the gaps MTA left behind, but as a separate, narrower signal, not a drop-in replacement.
Free Playbook
The Customer Data Strategy engagement model covers building a measurement approach that combines MTA, incrementality testing and platform-level signals into one coherent view, rather than treating any single method as the complete answer.
Get the Executive PlaybooksMulti-Touch Attribution: FAQ
Is data-driven attribution always better than rule-based models?
Only when there’s enough volume to train it reliably. Below a certain conversion threshold, a data-driven model doesn’t have enough signal to outperform a well-chosen rule-based model, and can produce results that look sophisticated but aren’t actually more accurate.
Should we abandon MTA given its blind spots?
No, but it shouldn’t run unpaired. MTA is still useful for the portion of the journey it can see. The fix for its blind spots is adding incrementality testing and offline matching alongside it, not discarding it entirely.
How often should an attribution model be reviewed?
Whenever the channel mix or tracking environment changes meaningfully, a new platform added, a major tracking restriction like ITP tightening further, rather than on a fixed annual schedule. The model should reflect what’s actually trackable now, not what was trackable when it was built.
